BACK OFF! After weeks of backlash, Meta has indefinitely delayed new commercial terms that would have required Meta Business account users to allow extensive AI training on outside websites linked on Facebook, Ars Technica reports.
“We’re pausing the changes as we continue to engage with stakeholders and take our time to get this right. In the meantime, our existing terms remain in effect,” a Meta spokesperson told Reuters.
Why publishers freaked out: legal experts warned Nieman Lab the vague language could let Meta ignore robots.txt scraping preferences and crawl huge amounts of off-Facebook content. Businesses had no way to opt out; keeping a Facebook page meant letting Meta crawl any linked site. The terms even required publishers to create test credentials so Meta’s bots could get past paywalls.
The pressure came from everywhere. The terms were first due October 30, then pushed to November 20. Courts in Brazil and Norway issued preliminary injunctions blocking them. The UK’s Competition and Markets Authority opened a formal investigation. In the US, Sens. Adam Schiff (D-Calif.) and Marsha Blackburn (R-Tenn.) asked Mark Zuckerberg to withdraw them.
Meta swapping the word “train” for “develop” didn’t help. “Does Meta think we can’t read?” wrote Theo Bamber, chief executive of the UK’s News Media Association. “It’s saying it can use all the content it scrapes to develop ‘any business product’. I mean, come on.” Meta says its crawling practices are unchanged and site owners can still use robots.txt, but Nieman Lab noted the revised terms never spelled that out.
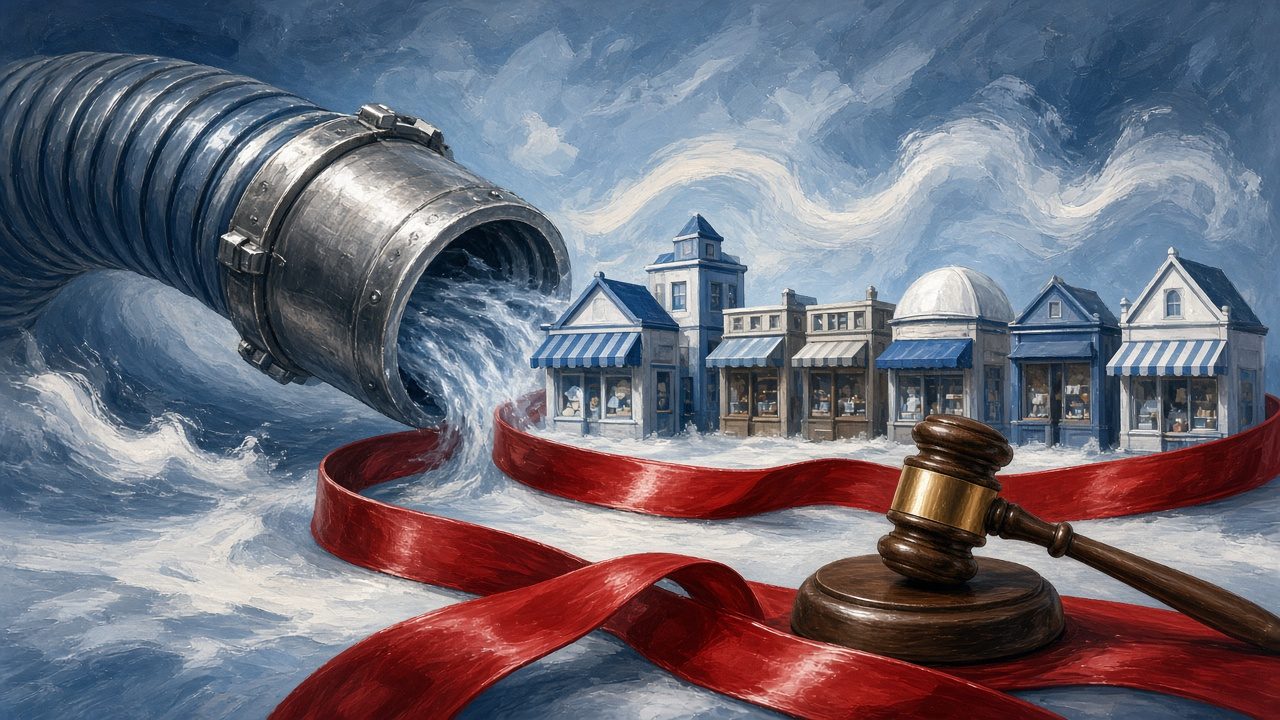
Featured image: AI-generated editorial illustration by Bugle Blast.
Source: Ars Technica (with reporting from Reuters and Nieman Lab)
Leave a Reply